Analytics, if you are happy with itAnalytics are off
We use analytics to see which pages are useful. Until you choose,
nothing is stored on your device and no identifier is created for
you. Declining changes nothing about how the site works.
Your browser is sending a Global Privacy Control signal, so
analytics storage stays off and we will not ask again.
Nothing. The HTML this page serves carries no readable main
text, so a crawler that does not run JavaScript receives an
empty page.
lantad.coWhat your browser renders
241 words
See the world for less
Hotels
Flights
Homes & Apts
Flight + Hotel
Activities
Airport transfer
Begin typing property name or keyword to search, use arrow keys or tab key to navigate, press Enter to select
12 Nov 2026
Thursday
13 Nov 2026
Friday
2 adults
1 room
Show me only entire homes and apartments
Add a flight
SEARCH
Top destinations in the United States
Las Vegas (NV)
1,113 accommodations
Los Angeles (CA)
4,491 accommodations
Dallas (TX)
1,813 accommodations
New York (NY)
3,049 accommodations
Orlando (FL)
17,408 accommodations
Phoenix (AZ)
3,922 accommodations
Houston (TX)
2,359 accommodati...
Show all 241 words
See the world for lessHotelsFlightsHomes & AptsFlight + HotelActivitiesAirport transferBegin typing property name or keyword to search, use arrow keys or tab key to navigate, press Enter to select12 Nov 2026Thursday13 Nov 2026Friday2 adults1 roomShow me only entire homes and apartmentsAdd a flightSEARCHTop destinations in the United StatesLas Vegas (NV)1,113 accommodationsLos Angeles (CA)4,491 accommodationsDallas (TX)1,813 accommodationsNew York (NY)3,049 accommodationsOrlando (FL)17,408 accommodationsPhoenix (AZ)3,922 accommodationsHouston (TX)2,359 accommodationsChicago (IL)1,444 accommodationsSan Francisco (CA)1,357 accommodationsAtlanta (GA)1,630 accommodationsSan Diego (CA)1,270 accommodationsAccommodation PromotionsView allFlights & Activities PromotionsProperties we think you'll likePopular destinations outside United StatesKuala Lumpur19,902 accommodationsManila13,223 accommodationsJakarta14,249 accommodationsPenang5,161 accommodationsDubai19,464 accommodationsBangkok12,048 accommodationsJohor Bahru6,994 accommodationsMalacca5,883 accommodationsKota Kinabalu3,417 accommodationsCebu5,254 accommodationsJohor Bahru6,994 accommodationsBangalore5,372 accommodationsBandung7,196 accommodationsBali32,908 accommodationsIpoh2,516 accommodationsGoa9,254 accommodationsCameron Highlands1,789 accommodationsKuching1,465 accommodationsMumbai4,177 accommodationsSingapore1,326 accommodationsSave 10% on your 1st app booking!Just scan the QR code for instant savings
lantad.co
27% of this page's content
never reaches an AI crawler.
64 words of the
241 a browser renders never reach
an AI crawler.
An assistant answering a question about this page never sees them.
Both panels are the main text of the same page, counted the same way
and fetched twice at the same moment: once as an AI crawler asks for
it, with no JavaScript, and once in a real browser.
The panel with more text than fits opens to the full text.
Text only one side has is highlighted.
Passages an AI crawler never receives
20 wordsBegin typing property name or keyword to search, use arrow keys or tab key to navigate, press Enter to selectabout +4.1 on the score
8 wordsJust scan the QR code for instant savingsabout +1.7 on the score
7 wordsShow me only entire homes and apartmentsabout +1.5 on the score
7 wordsSave 10% on your 1st app booking!about +1.5 on the score
6 wordsTop destinations in the United Statesabout +1.2 on the score
3 further
passages are highlighted
in the browser panel above.
Longest first. A passage counts as missing when its text appears
nowhere in the HTML a crawler receives, so a block that merely
moved is not listed. Lines under 4 words are not
judged either way, because a match on "Get Started" would be
chance rather than evidence.
Why a crawler does not get this, and the fix
When an AI crawler visits your page it receives a nearly empty shell, because your words only appear after a browser runs the site's code, which crawlers do not do.
The fix
Server-side render or statically generate the page so the main content ships in the initial HTML.
Four weighted parts, and the arithmetic is on the page. Nothing here
is rounded in your favour, and anything the scan could not measure
says so rather than being folded in as a guess.
AI crawlers see little of what your visitors see.
!
A critical issue is holding this page back. The grade above does
not tell the whole story: start with the critical item below.
Retrievability, measured at 0%, sits beside the
score rather than inside it: it checks whether the rendered words can be
recovered from the crawler's HTML at all, including from JSON data blocks,
and it informs the findings below without adding points.
This page scores higher than 4% of the
1,174 sites we have measured.
That puts it in the bottom 10 percent.
See the index.
Not indexed; share this link freely.
Save it as a PDF with your browser's print (Cmd or Ctrl + P) for a client-ready copy.
The link carries a short share code so Lantad can count how many people a share
brought back. It holds no name, email or address. LinkedIn builds its preview from the card
above; on X the text opens in the composer for you to change.
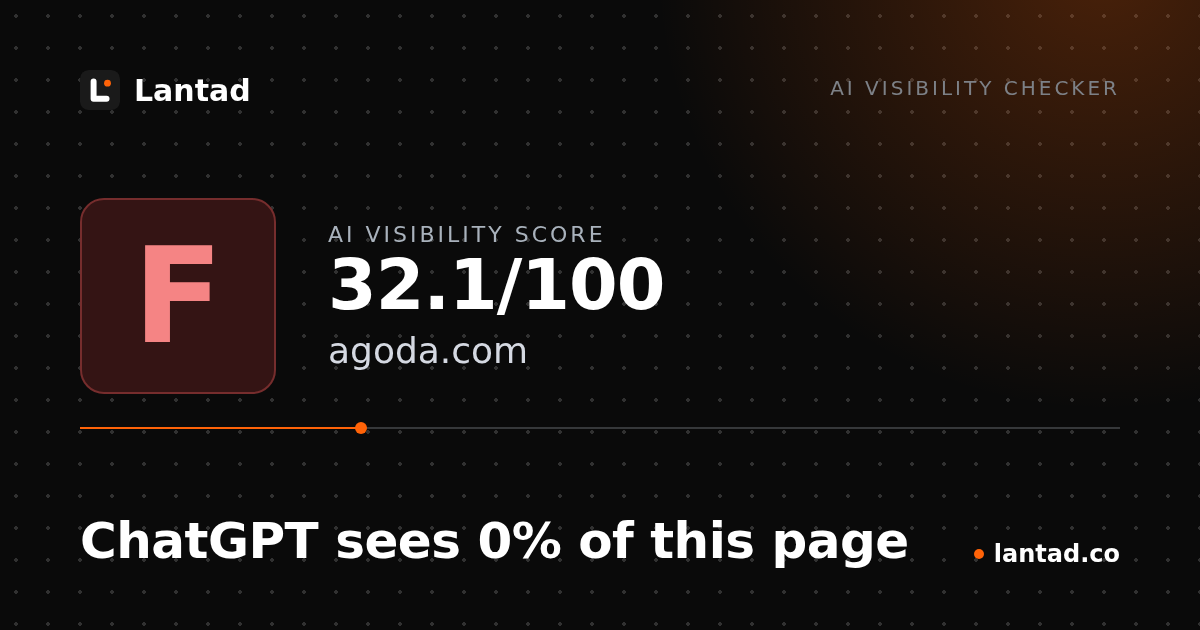
This homepage is 47.9 points short of the
80 that unlocks a score badge. Do this first
lists the quickest fixes; scan again once they are live.
See if AI recommends you
We ask one AI engine three questions a buyer would ask about your kind of business, and show you
whether agoda.com is named, who is named instead, and the sources it cites. Free, one per email.
We use the email only to send that one link and to keep it to one free check per address.
Your next move
Do this first
8 things are holding this page back. These are the 3 worth doing first, in order.
1
Critical
Main content is invisible to AI crawlers
Server-side render or statically generate the page so the main content ships in the initial HTML.
AI assistants cannot see what you sell or say, so when a buyer asks about your kind of business they get told about competitors whose pages are readable and you are left out entirely.
With no reliable name to attach to the page, AI assistants struggle to identify or cite it, so you can be left out when a buyer asks about what you do.
Estimated gain is the sub-score arithmetic applied to this page, not
a prediction about citations.
Clearing the first item alone would move this page from 32.1 to
at most 82.1.
Fixed something? Prove it.
We re-measure this page now and show the before and after side by
side, including the parts that did not move. One re-check per report.
What to know about this measurement
1 note on what was and was not measured
A cookie consent overlay (CybotCookiebotDialog) was still present at extraction; some rendered text may sit behind it.
The rendered page
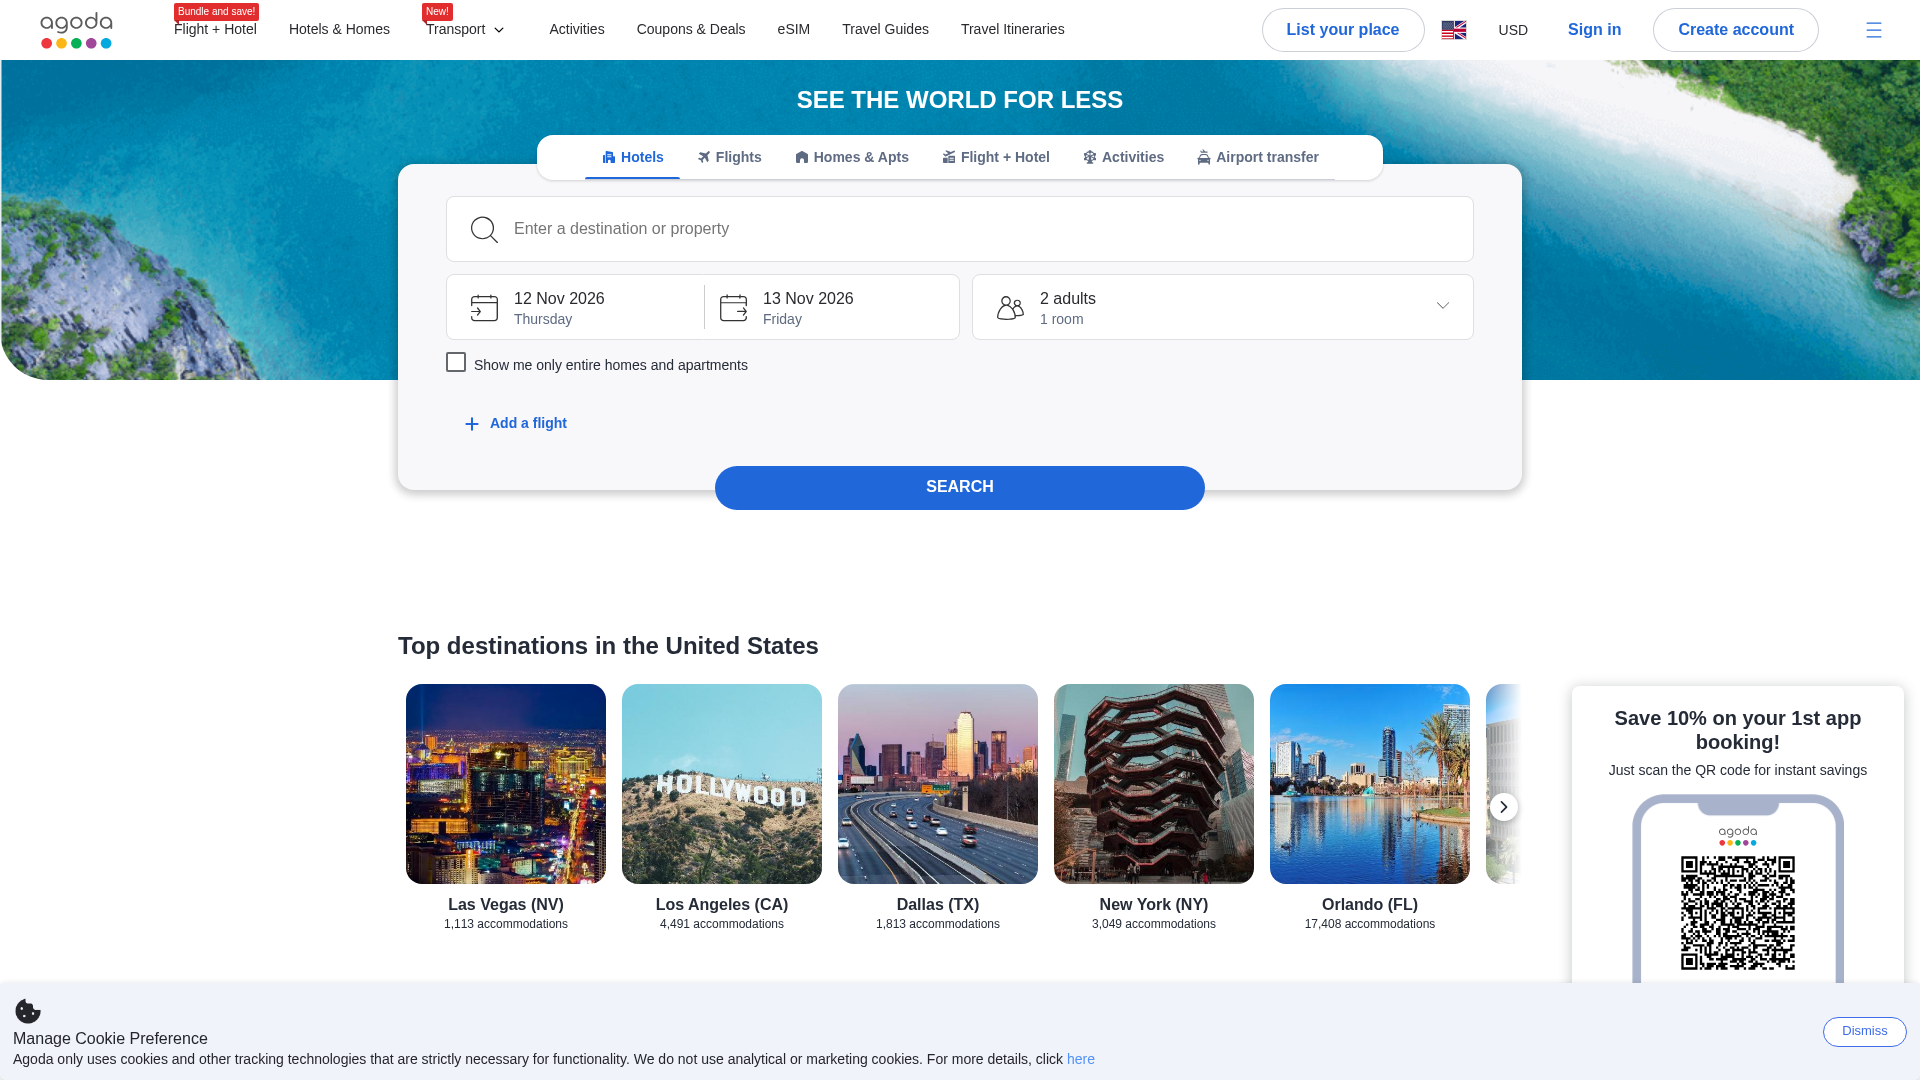
How this page looked in a real browser at scan time
How the page looked in a real browser at scan time. The measurements
come from the extracted text above, not from this image.
Bot access matrix
All 15 AI crawlers we track can reach this page
Every AI crawler we track, and what your site does when it asks for
this page. Turning a model training crawler away is a choice, not a
fault, so those are marked apart from the blocks that cost you score.
Every AI crawler in this list can reach this page.
15 / 15named crawler tokens allowed in robots.txt
12 / 12live probes got the page (HTTP 2xx)
3rule-only or not probed, so no server response to read
Reaching a page is not the same as reading it. The crawlers marked
allowed here are let in and receive the same HTML a browser gets,
but on this page that HTML is a near-empty shell until JavaScript
runs. What they can actually read is scored separately: see
Main content is invisible to AI crawlers
below.
✓
All 15 AI crawlers we track reach this page normally.
Show them
The AI crawlers that reach this page normally.
Crawler
Purpose
Status
robots.txt
Server response
GPTBotOpenAI
PurposeTraining
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
OAI-SearchBotOpenAI
PurposeAI search
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
ChatGPT-UserOpenAI
PurposeAssistant
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
ClaudeBotAnthropic
PurposeTraining
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
Claude-SearchBotAnthropic
PurposeAI search
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
Claude-UserAnthropic
PurposeAssistant
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
anthropic-aiAnthropic
PurposeTraining
✓
Allowed
robots.txtallowed
Server responseno request user agent exists to test
PerplexityBotPerplexity
PurposeAI search
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
Perplexity-UserPerplexity
PurposeAssistant
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
Google-ExtendedGoogle
PurposeTraining
✓
Allowed
robots.txtallowed
Server responseno request user agent exists to test
Applebot-ExtendedApple
PurposeTraining
✓
Allowed
robots.txtallowed
Server responseno request user agent exists to test
Meta-ExternalAgentMeta
PurposeTraining
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
BytespiderByteDance
PurposeTraining
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
CCBotCommon Crawl
PurposeTraining
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
AmazonbotAmazon
PurposeTraining
✓
Reaches your page
robots.txtallowed
Server responsesame page served (HTTP 200)
✓
Reaches your page
Your robots.txt allows this crawler and your server returned it the same page it returns to a browser. This measures access, not content: whether that HTML is readable without JavaScript is a separate check, scored as retrievability when the page can be graded.
✓
Allowed
Your robots.txt allows this token. It is a robots.txt token only: it sends no user agent of its own, so there is no server response to test and none is implied.
AI-readiness checklist
2 of 7 basics in place
The page basics an assistant needs, checked against what an AI
crawler receives rather than the rendered page. These feed the
Structure part of the score above.
✗Title tagNo title tag. It is the first thing an assistant names your page by; add one.Needs work
✗Meta descriptionNo meta description. It is the summary an assistant may quote; add one under 155 characters.Needs work
✗One H1 headingNot exactly one H1. A crawler reads the page subject from its single H1; use one.Needs work
✗Canonical URLNo canonical link. It tells a crawler which URL is the real one; add rel=canonical.Needs work
✓Heading coverageHeadings cover the content, so a crawler can index it by section.Pass
✓No wall of textNo single block is too long to parse cleanly.Pass
✗llms.txtNo llms.txt. It is informational only, a nice-to-have rather than a ranking factor.Needs work
✓
Structured data
Found Organization, WebSite, but only after JavaScript ran, which a crawler may not see.
Pass
What is holding you back, worst first
Ranked by severity, worst first. Start at the top: fix the
critical items and the rest compounds.
Critical
Main content is invisible to AI crawlers
csr_blankup to +50
AI assistants cannot see what you sell or say, so when a buyer asks about your kind of business they get told about competitors whose pages are readable and you are left out entirely.
What this means for you
When an AI crawler visits your page it receives a nearly empty shell, because your words only appear after a browser runs the site's code, which crawlers do not do.
The fix, technically
Server-side render or statically generate the page so the main content ships in the initial HTML.
Evidence from your pageOnly 0% of the rendered main content exists in the initial HTML (241 rendered tokens vs 0 raw tokens).
Fix the rendering gap. We move the content AI engines miss into the initial HTML: server rendering, static generation, or hydration restructuring, measured before and after with this scanner.
With no reliable name to attach to the page, AI assistants struggle to identify or cite it, so you can be left out when a buyer asks about what you do.
What this means for you
When an AI crawler first loads your page, it finds no title telling it what the page is called.
The fix, technically
Ship a unique, descriptive title tag server-side.
Evidence from your pageNo <title> element in the initial HTML.
Make the page extraction friendly. Titles, headings, and block structure decide how retrieval systems chunk and quote you. We restructure pages so the right passages surface.
AI crawlers capture the page before that summary appears, so your core facts never reach them and you go unmentioned.
What this means for you
The labeled summary of your key business facts is added only after your page finishes loading in a visitor's browser.
The fix, technically
Your JSON-LD appears only after JavaScript runs, so AI crawlers never see it. Emit it in the initial HTML.
Evidence from your pageJSON-LD appears in the rendered DOM but not in the initial HTML.
Ship structured data that parses. We add server-rendered JSON-LD with the required properties for your content types, validated by the same checker that graded this page.
AI assistants are left to guess how to describe you and may summarize you inaccurately or favor a competitor whose page states its purpose clearly.
What this means for you
Your page carries no short summary sentence describing what it is about.
The fix, technically
Add a server-rendered meta description.
Evidence from your pageNo meta description in the initial HTML.
Minor
Page does not have exactly one H1
h1_count+2.3
AI crawlers can misread the page's main subject, weakening how confidently they match it to the questions buyers actually ask.
What this means for you
Your page is missing a single clear main heading that says what it is about, or it has several competing ones.
The fix, technically
Use a single H1 stating what the page is about.
Evidence from your pageFound 0 H1 elements in the initial HTML.
Minor
No canonical URL in the initial HTML
missing_canonical+2.3
When the same content sits at more than one address, AI assistants may credit a duplicate instead of your real page, splitting or losing the visibility you have earned.
What this means for you
Your page does not tell AI crawlers which web address is the official one for this content.
The fix, technically
Add an absolute self-referencing canonical link.
Evidence from your pageNo canonical link in the initial HTML.
Minor
No llms.txt
no_llms_txt+1.2
A handful of assistants will read this file if it exists, so adding it gives you a small extra chance of being understood correctly at no cost, though most tools ignore it today.
What this means for you
Your site does not include the optional plain-text guide that some AI assistants look for to understand what your business is about.
The fix, technically
Informational only. Independent 2026 data (Ahrefs, SE Ranking, Google documentation) shows no measurable citation effect from llms.txt. It is checked because it costs nothing and some assistants read it, but it moves neither crawling nor ranking.
Evidence from your pageNo llms.txt at the site root.
Minor
URL redirects off the original domain
offsite_redirect
The scores here describe that other site, so your own page is not the one AI is reading about you.
What this means for you
The web address you entered sends visitors to a different website.
The fix, technically
The scanned URL redirects to a different domain; scores describe the final target.
Evidence from your pageagoda.com redirected to www.agoda.com (1 hop(s)).
Review your crawler access policy. We map which AI systems you are blocking, deliberately or by accident, and align robots.txt, CDN rules, and directives with the visibility you actually want.
You are not guessing at this. Across 1,174 sites
in our live AI Visibility Index, the average score is
74/100. This report shows exactly where agoda.com stands.
Do it yourself
Get your whole site audited with a reviewed, ranked fix plan you
can hand to your dev, plus 3 months of monitoring. Delivered in
3 business days.
We parsed the JSON-LD in the HTML a no-JavaScript crawler receives and checked five properties of the identity it declares. This measures your markup, not any AI system's behavior: nobody outside those systems can observe what they do with a given property, so nothing here is a prediction. Scored separately from your 32.1/100 score.
0/100Not declaredNo identity node in the HTML a crawler receives.0 of 5 signals present
+Missing: Identity declaredAn identity node exists in the rendered DOM but not in the HTML a crawler receives, so a crawler that does not run JavaScript gets nothing here. Emit the same JSON-LD in the initial HTML.
+Missing: External identifiers (sameAs)Measured on the identity node, and no identity node was found. Declare one first, then add sameAs URLs to it.
+Missing: Stable identifier (@id)Measured on the identity node, and no identity node was found. Declare one first, then give it an absolute @id.
+Missing: Logo declaredMeasured on the identity node, and no identity node was found. Declare one first, then add logo as a full https URL.
+Missing: Category declaredMeasured on the identity node, and no identity node was found. Declare one first, then state a category as a specific type, a standard industry code, or a resolvable additionalType URL.
Starting point for your identity block
Built from this scan: the URL we resolved, plus one property for each signal above that we did not find. Every REPLACE_ value is a placeholder, so edit them before you ship this. We do not guess names, logos, profile links or categories, so nothing here is invented.
Your identity node exists in the rendered DOM but not in the HTML a crawler receives, so this belongs in the initial HTML your server sends, not in a script that writes it later.
What each signal measures, the weights, and the sample behind them:
the methodology page.
llms.txt
This site serves none
This site serves no llms.txt.
Informational only. Independent 2026 data (Ahrefs, SE Ranking, Google documentation) shows no measurable citation effect from llms.txt. It is checked because it costs nothing and some assistants read it, but it moves neither crawling nor ranking.
Keywords and prompts
Derive the questions people ask AI assistants where this page
could be the answer, scored by how much of each the page actually
covers, then test whether a named model brings the brand up at
all. The scan you are reading is free and anonymous; this check
asks a real model live, so it asks for an email.
Not measured on this run
What a paid plan adds for this page
These four tools run on agoda.com on any paid plan. They are listed as
capabilities, not as a preview: none of it has been measured for this
report, so nothing is shown. Everything above stays free.
Locked
Prompt tracking over time
Your prompt set re-run every week with the history kept, the competitors models name instead, and 10 prompts per run.
Locked
Score history
Every past score for this page in one dated chart, linked back to the report behind each point.
Locked
Whole-site audit
Every page on agoda.com checked and ranked worst first, with a CSV.
Locked
API and MCP
Run this same check from your own code, or from Claude and ChatGPT.
Starter is $59/mo and watches 1,000 pages
across 10 sites. Nothing on this report is withheld to sell it.
See what a plan adds
Keep agoda.com readable to AI
This report is a snapshot. Parity regressions are silent, because
nothing looks wrong in a browser, so the way they get caught is a
re-check after every deploy rather than a person remembering to look.
Free: get told if it slips
AI visibility drops silently after a redeploy or a CDN tweak. Get one
email if agoda.com drops, plus a weekly summary either way. No spam.
Free tier watches 25 pages across 3 sites,
re-checked weekly, with a drift alert when a page drops more than 6 points.
Starter · $59/mo
Or find out before your customers do
We tell you what broke, and what it cost you. Not just that a number moved: the words that stopped reaching crawlers, the crawler that lost access, and the likely reason.
Every week, on this page and up to 1,000 more, with the history to show when it happened
See the AI prompts this page could answer, and the keyword angles you are missing
Audit your whole site: every page checked, worst first, with a CSV